

Zyphra
Zyphra is an American artificial intelligence research and product company headquartered in San Francisco, California, that also hires staff based in London.[1] The company builds open-weight foundation models, specializing in hybrid architectures that combine state space models with attention mechanisms, sparse mixture of experts (MoE) designs, and efficient training systems, and since May 2026 it has also run Zyphra Cloud, an AMD-based platform for hosting and serving open models.[1][45] Its co-founders include chief executive Krithik Puthalath and chief scientist Beren Millidge.[4][59] IBM said in October 2025 that Zyphra had recently closed a Series A round at a $1 billion valuation.[9] In May 2026 Forbes reported, citing sources, that the company was raising a further $500 million at a valuation of at least $5 billion in a round that included a commitment from AMD.[49]

Zyphra is best known for the Zamba family of hybrid Mamba-Transformer large language models, the Zonos text-to-speech models, and the ZAYA1 family of MoE models, including the ZAYA1-8B reasoning model released on May 6, 2026.[2] The ZAYA1 models were pretrained on AMD Instinct MI300X GPUs on a cluster built with IBM; Zyphra described the November 2025 ZAYA1-base preview as the first large-scale MoE foundation model trained entirely on an integrated AMD platform.[41] The company has also published research on Tree Attention, Compressed Convolutional Attention (CCA), and the Zyda training data corpus, and in 2026 released ZUNA, a foundation model for EEG brain signals.[24][27][28][51]
Company background
Zyphra describes its mission as building open superintelligence, arguing that "intelligence should not be controlled by a few."[1] Published accounts give different founding years: VentureBeat wrote in May 2026 that the company was founded in 2021, while a 36Kr report the same month said 2020.[4][65] Beren Millidge's CV dates his own role as co-founder and chief scientist from July 2023, after he left Apollo Research, which he had co-founded in May 2023, "to start Zyphra."[60] Debarghya Das's "Ultimate Neolab List" names four founders: Krithik Puthalath, Danny Martinelli, Tomas Figliolia, and Beren Millidge; the business-data provider Dealroom names Puthalath and Martinelli as founders.[67][66]
Krithik Puthalath serves as chairman and chief executive officer.[9] A 2024 version of Zyphra's team page listed his background as theoretical physics and electrical engineering at the University of Illinois, followed by work at Cambridge Quantum and IBM Almaden.[61] Beren Millidge, the co-founder and chief scientist, leads the technical teams.[14][59] He completed a PhD in machine learning and computational neuroscience at the University of Edinburgh and was a postdoctoral researcher in computational neuroscience at the University of Oxford, working with Rafal Bogacz on predictive coding, before serving as head of research at Conjecture.[14][60] The same 2024 team page listed Tomas Figliolia with a PhD in electrical engineering from Johns Hopkins and prior work at Apple, Xilinx, and Qualcomm, and Danny Martinelli with an economics degree from Illinois.[61] Figliolia is the first author of the company's Compressed Convolutional Attention paper.[27]
Quentin Anthony, whom the 2024 team page listed with a PhD in computer science from Ohio State and prior work at EleutherAI and Stability AI, is not listed among the founders but is an author on most Zyphra technical reports, including Zamba, Zamba2, the ZAYA1 AMD training report, and ZAYA1-8B.[61][15][20][39][37] The ZAYA1-8B technical report lists 18 named authors.[5]
| Person | Role at Zyphra | Background (per cited source) |
|---|---|---|
| Krithik Puthalath | Co-founder, chairman and CEO[4][9][45] | Theoretical physics and EE (Illinois); Cambridge Quantum; IBM Almaden[61] |
| Beren Millidge | Co-founder and chief scientist[59][60] | PhD (Edinburgh); Oxford postdoc; Conjecture; Apollo Research co-founder[60] |
| Tomas Figliolia | Listed as a founder by Das[67] | PhD EE (Johns Hopkins); Apple, Xilinx, Qualcomm[61] |
| Danny Martinelli | Listed as a founder by Dealroom and Das[66][67] | Economics (Illinois)[61] |
| Quentin Anthony | Researcher; author on most technical reports[37][39] | PhD CS (Ohio State); EleutherAI, Stability AI[61] |
The company operates two divisions: Zyphra Research, which it describes as a lab "training multimodal open models on heterogeneous compute," and Zyphra Cloud, a full-stack AI platform built on AMD hardware.[1] Zyphra was based in Palo Alto in its early years, with what its 2024 site called a growing presence in Montreal and London.[61] By October 2025 IBM described it as based in San Francisco, and its website lists an office at 415 Mission Street in San Francisco and says it hires in San Francisco and London.[9][1]
Funding and partnerships
The Information reported on January 31, 2025 that Zyphra, then based in Palo Alto, was in talks to raise $100 million in Series A funding at a $1 billion valuation, and that returning investor Metaplanet, which manages investments for Skype founding engineer Jaan Tallinn, was in talks to lead the round.[11] Tallinn had led Anthropic's $124 million Series A in 2021.[63] IBM's October 2025 announcement stated that Zyphra "recently closed a Series A financing round at a $1B valuation."[9] Forbes, citing PitchBook, reported in May 2026 that Zyphra had raised $110 million at a $1 billion valuation in 2025, with investors including Steve Jurvetson's Future Ventures, Jaan Tallinn, and Bison Ventures.[49] VentureBeat, also citing PitchBook, dated the round to June 2025.[4]
A second pillar of the company's strategy is hardware. On October 1, 2025, IBM and AMD jointly announced a multi-year collaboration with Zyphra to deliver dedicated AI training infrastructure on IBM Cloud.[9] The agreement is the first large-scale dedicated training cluster on IBM Cloud built around AMD Instinct MI300X GPUs, paired with AMD Pensando Pollara 400 AI NICs and AMD Pensando Ortano DPUs.[9][10] The initial deployment was made available to Zyphra in early September 2025, with expansion planned in 2026.[9] Puthalath described the deal as the first time AMD's full-stack training platform had been integrated and scaled on IBM Cloud.[9]
In May 2026 Zyphra launched Zyphra Cloud on AMD Instinct MI355X GPUs hosted by TensorWave, a cloud provider backed by AMD Ventures, in what the announcement presented as a partnership with AMD.[45] On May 19, 2026, Forbes reported that Zyphra was raising $500 million in a new round that included a commitment from AMD, with some sources saying the valuation would be at least $5 billion; Zyphra declined to comment and AMD did not respond.[49] Reuters carried the Forbes report the same day.[50] Forbes also reported that the company had told investors Zyphra Cloud would provide computing capacity to compute-constrained frontier labs such as Anthropic, Meta, and OpenAI.[49] Zyphra's own list of announcements contained no funding announcement as of late October 2026, so the size, terms, and closing of the round were not confirmed by the company.[58]
Zyphra has also worked with other hardware vendors: in May 2026 it published work, done in collaboration with AWS, on tensor-parallel communication overlap for inference on AWS Inferentia2 chips.[58]
Funding history
| Round | Date | Amount | Lead or notable investors | Valuation |
|---|---|---|---|---|
| Earlier rounds | Before 2025 | Not disclosed | Metaplanet (described as a returning investor in January 2025)[11] | Not disclosed |
| Series A | Closed in 2025 (June 2025 per PitchBook, via VentureBeat)[4] | $100 million reported in talks (The Information); $110 million per PitchBook (via Forbes)[11][49] | Metaplanet in talks to lead (The Information); investors include Future Ventures, Jaan Tallinn, Bison Ventures (PitchBook via Forbes)[11][49] | $1 billion[9][49] |
| Strategic infrastructure | October 1, 2025 | Not disclosed | IBM and AMD (multi-year compute agreement) | n/a[9] |
| Series B (reported, not announced) | May 2026 | $500 million being raised (Forbes) | Includes a commitment from AMD | At least $5 billion, per sources cited by Forbes[49] |
Research focus and product portfolio
Zyphra's technical work clusters around four ideas. First, hybrid architectures that pair the Mamba state space model with attention layers, trading dense self-attention for lower latency and a smaller key-value cache.[15] Second, sparse MoE designs that lift total parameter count without scaling active compute.[5][56] Third, efficient attention and parallelism methods such as Tree Attention and Compressed Convolutional Attention.[24][27] Fourth, large open training datasets, distributed through the Zyda series.[28] These threads feed into one another; ZAYA1-8B, for example, draws on CCA for attention compression, on the MoE++ recipe for routing and load balancing, and on a four-stage reinforcement learning cascade with a custom test-time compute method called Markovian RSA.[5][37] The company's current research page lists three pillars: next-generation architectures for long-context reasoning, long-term memory and continual learning; multimodal models across language, audio and vision; and co-design of models and kernels across heterogeneous hardware.[58]
Most of the company's model releases are open-weight, usually under the Apache 2.0 license, with weights, inference code, and in most cases a technical report.[6][58] Exceptions to the Apache pattern include the Zyda datasets, released under ODC-By, and ZR1-1.5B, a fine-tune of DeepSeek-R1-Distill-Qwen-1.5B released under the MIT license.[30][57]
Model timeline
Zyphra's model releases span language, audio, vision, and brain signals. The table below summarizes the main releases through October 2026.
| Release | Date | Type | Parameters | License |
|---|---|---|---|---|
| BlackMamba | February 2024 | Mamba-MoE language models | 340M active / 1.5B total and 630M active / 2.8B total | Apache 2.0[56][72] |
| Zamba-7B | April 2024 | Hybrid Mamba1-Transformer LLM | 7B | Apache 2.0[16] |
| Zyda | June 2024 | Pretraining dataset | 1.3T tokens | ODC-By[28][30] |
| Zamba2-2.7B | July 2024 | Hybrid Mamba2-Transformer LLM | 2.7B | Apache 2.0[19] |
| Tree Attention | August 2024 | Research paper and library | n/a | MIT (code, per repository README)[26] |
| Zamba2-mini (1.2B) | August 2024 | Hybrid LLM for on-device | 1.2B | Apache 2.0[18] |
| Zamba2-7B | October 14, 2024 | Hybrid Mamba2-Transformer LLM | 7B | Apache 2.0[17][21] |
| Zyda-2 | October 2024 | Pretraining dataset | 5T tokens | ODC-By[31] |
| Zonos-v0.1 | February 10, 2025 | Text-to-speech (transformer and SSM hybrid) | 1.6B each | Apache 2.0[33] |
| ZR1-1.5B | April 2025 | Small reasoning model (RL fine-tune) | 1.5B | MIT[57][58] |
| Compressed Convolutional Attention | October 2025 | Research paper | n/a | n/a[27] |
| ZAYA1-base | November 24, 2025 | Base MoE (preview) | 760M active / 8.3B total | Apache 2.0[39][41][42] |
| ZUNA | February 18, 2026 | EEG foundation model | 380M | Apache 2.0[51] |
| ZAYA1-8B | May 6, 2026 | Reasoning MoE | 8.4B total / 760M active | Apache 2.0[6] |
| ZAYA1-74B-Preview | May 7, 2026 | Pre-RL reasoning-base MoE | 74B total / 4B active | Apache 2.0[43] |
| ZAYA1-VL-8B | May 8, 2026 | Vision language MoE | 9.2B total / 1.4B active (incl. vision encoder) | Apache 2.0[7][38] |
| ZAYA1-8B-Diffusion-Preview | May 14, 2026 | Diffusion language model (research preview) | Based on ZAYA1-8B | n/a[44] |
| Zamba2-VL | June 2, 2026 | Hybrid SSM vision language models | 1.2B, 2.7B, 7B | Apache 2.0[55] |
| ZONOS2 | June 12, 2026 | MoE text-to-speech | 900M active / 8B total | Apache 2.0[53] |
| ZUNA1.1 | July 16, 2026 | EEG foundation model | 380M | Apache 2.0[52][58] |
Zamba and Zamba2 model family
Before Zamba, Zyphra released BlackMamba in February 2024, an architecture that combined Mamba with a mixture-of-experts layer; the company open-sourced 1.5B and 2.8B-parameter versions trained on 300 billion tokens.[56] In April 2024 VentureBeat, which called BlackMamba the company's first model, reported that Millidge described it as the equivalent of a "toy" that proved out the company's architecture experiments.[35]
The Zamba family was Zyphra's first major release and remains its most cited line of work. The original Zamba-7B was announced on April 16, 2024 and accompanied by an arXiv paper, "Zamba: A Compact 7B SSM Hybrid Model" (arXiv:2405.16712), published on May 26, 2024.[15][16] The model uses a backbone of Mamba state space layers with a single shared attention block, applied every six Mamba blocks, whose weights are reused across the network.[15][62] The shared attention design lets the model gain global mixing without paying the parameter cost of a full per-layer transformer.[15] Zyphra said the model was built by a team of seven people on 128 H100 GPUs in 30 days.[16]
Zyphra reported that Zamba-7B approached the performance of Mistral and Gemma despite being trained on many times fewer tokens, and outperformed LLaMA-2 7B and OLMo-7B across a broad set of standard benchmarks while using less than half of their training data.[16][35] The model was open-sourced under Apache 2.0 along with all training checkpoints, an unusual choice that let researchers study the trajectory of capability emergence.[16]
The second generation, Zamba2, replaced the Mamba1 backbone with Mamba2 blocks.[20] Mamba2 is a refinement of the original state space architecture; Zyphra said Mamba2 blocks have roughly four times the throughput of an equal-parameter transformer block.[17] The Zamba2 suite shipped in three sizes:
- Zamba2-2.7B: released on July 28, 2024 (the company's post calls it Zamba2-small), this size uses two interleaved shared attention blocks in an ABAB pattern and is positioned as a mid-scale efficient model.[19]
- Zamba2-mini (1.2B): announced on August 27, 2024, this variant uses a single shared attention block rather than two interleaved blocks, which Zyphra said gives a higher FLOP count at a given parameter budget; it targets on-device inference.[18][23]
- Zamba2-7B: released on October 14, 2024, this is the flagship of the Zamba2 family, also using two shared attention blocks.[17] Zyphra reported 25% faster time-to-first-token and a 20% improvement in tokens-per-second compared to Llama3-8B, with substantially lower memory usage.[17] The Mistral v0.1 tokenizer was used across the Zamba2 models.[20][22][23]
A core architectural quirk of Zamba2 is that it stores key-value caches only for invocations of the shared attention block, not for every layer.[20] At a 1:6 ratio of Mamba2 to attention, this cuts KV-cache memory by a factor of roughly six compared with a pure transformer.[20] Non-shared LoRA projectors are applied to the shared blocks to give each invocation some depth specialization without inflating parameter counts: on the shared MLPs in the 2.7B and 7B models, and on both the shared attention and MLP blocks in the 1.2B model.[20]
Zamba family parameter counts
| Model | Total parameters | Pretraining tokens | Mamba variant | Shared attention blocks | Tokenizer |
|---|---|---|---|---|---|
| Zamba-7B (v1) | 7B | ~1T + ~50B annealing | Mamba1 | 1 (every 6 Mamba blocks) | Mistral v0.1[15][62] |
| Zamba2-mini (1.2B) | 1.2B | 3T + 100B anneal | Mamba2 | 1 | Mistral v0.1[18][23] |
| Zamba2-2.7B | 2.7B | 3T + 100B anneal | Mamba2 | 2 (ABAB) | Mistral v0.1[19][22] |
| Zamba2-7B | 7B (7.4B per technical report) | ~3T + 100B anneal | Mamba2 | 2 (ABAB) | Mistral v0.1[17][20] |
The Zamba2 technical report was published on arXiv as 2411.15242 in November 2024 with authors Paolo Glorioso, Quentin Anthony, Yury Tokpanov, and collaborators.[20] In June 2026 Zyphra extended the line to vision with Zamba2-VL, a family of vision-language models at 1.2B, 2.7B, and 7B parameters built on the Zamba2 backbone, which the company said were competitive with Transformer-based vision-language models of similar size while delivering roughly an order of magnitude lower time-to-first-token.[55]
Tree Attention
Tree Attention is a research result first published in August 2024, with the paper "Tree Attention: Topology-aware Decoding for Long-Context Attention on GPU clusters" (arXiv:2408.04093).[24] The work was a collaboration between Zyphra researchers and EleutherAI, and the code is hosted at github.com/Zyphra/tree_attention, whose README carries an MIT license badge.[24][26]
The paper makes two contributions. First, it derives a scalar energy function whose gradient computes the self-attention block, drawing a connection between attention and energy-based models such as Hopfield networks.[24][25] Second, and more practically, it exploits a structural property of attention that prior work had not put to use. The reduction of the logsumexp and max operators across the sequence axis is associative, which means it can be computed in parallel via an associative scan, a tree reduction for decoding, similar to state space models.[25]
In distributed decoding on GPU clusters, this lets attention be computed using a tree reduction with logarithmic depth in the number of devices, rather than the linear depth of ring attention.[24][25] The reported result is up to 8x faster cross-device decoding than ring attention, with significantly lower communication volume and 2x lower peak memory.[24][25] The paper also reports decoding speedups of up to 4x on Llama 3.1-8B, and demonstrations on H100 DGX nodes, AMD MI300X nodes, and PCIe-connected RTX 4090s.[24] Zyphra later listed Tree Attention among the parallelism and communication methods in its own production inference stack on AMD MI355X GPUs.[47]
Compressed Convolutional Attention
Compressed Convolutional Attention (CCA) is a more recent attention variant, introduced in October 2025 in arXiv:2510.04476 by Tomas Figliolia, Nicholas Alonso, Rishi Iyer, Quentin Anthony, and Beren Millidge.[27] CCA down-projects queries, keys, and values into a shared low-dimensional latent space and performs the entire attention operation inside that latent.[27] The compression factor controls a tradeoff that reduces parameters, KV cache, and FLOPs in a single move.[27]
A convolution over the sequence and channel axes is applied to the compressed Q and K latents, which is the source of the "convolutional" name.[27] The paper reports that this additional mixing lets CCA match or exceed multi-head latent attention (MLA) and standard multi-head attention (MHA) on quality metrics.[27] An extension called Compressed Convolutional Grouped Query Attention (CCGQA) adds GQA-style head sharing inside the latent space and yields a further 2x KV cache reduction without measurable performance loss.[27]
On an MoE workload, CCGQA achieves 8x KV cache compression with no drop in performance relative to MHA.[27] On H100 GPUs, the fused CCA/CCGQA kernel cuts prefill latency by roughly 1.7x at a 16k sequence length compared to MHA.[27] CCA is the attention method used inside the ZAYA1 models, and the kernel work formed the foundation for their efficient inference profile.[5][42]
ZAYA1-base
On November 24, 2025, Zyphra announced a preview of ZAYA1, together with a technical report on training foundation models on a full-stack AMD platform.[40][39] The company described ZAYA1-base, an MoE model with 760 million active and 8.3 billion total parameters, as the first large-scale MoE foundation model trained entirely on an integrated AMD platform: AMD Instinct MI300X GPUs, AMD Pensando networking, and the ROCm software stack.[41][39] It was trained for 14 trillion tokens in three phases, moving from mostly unstructured web data toward mathematical, coding, and reasoning data, using the Muon optimizer.[40] The model uses the Gemma3 tokenizer.[42]
The base model introduced the main architectural pieces later used in ZAYA1-8B: CCA attention; a router that replaces the usual linear router with a down-projection, a depth-mixing layer, and a three-layer MLP per expert; and learnable residual scaling.[42] According to the technical report, ZAYA1-base performed comparably to Qwen3-4B and Gemma3-12B and outperformed Llama-3-8B and OLMoE across reasoning, mathematics, and coding benchmarks.[39] The report also includes microbenchmarks of the MI300X and its Pollara networking, and transformer sizing rules tuned for the MI300X.[39]
ZAYA1-8B
ZAYA1-8B is Zyphra's first reasoning-focused MoE and was announced on May 6, 2026.[2] According to its model card, the model has 8.4 billion total parameters but only 760 million active parameters per forward pass; the technical report rounds these to 8 billion and 700 million.[6][37] It is built on an architecture the company calls MoE++, which combines several choices the company introduced in earlier work:[37]
- Compressed Convolutional Attention as the attention primitive, providing 8x KV-cache compression compared to standard attention.[27][4]
- MLP-based expert router with PID-controller bias balancing, replacing the linear router common in earlier MoE designs and improving routing stability across training.[5][4]
- Learned residual scaling, which manages residual stream norm growth as the network gets deeper.[5]
Reasoning data was included from pretraining onward, using what the technical report calls an answer-preserving trimming scheme.[37] Zyphra describes ZAYA1-8B as the first MoE model pretrained, midtrained, and supervised fine-tuned on an AMD Instinct MI300 stack.[5] After a supervised fine-tuning phase, post-training uses a four-stage reinforcement learning cascade: a reasoning warmup on math and puzzles, a 400-task RLVE-Gym curriculum, math and code RL with test-time compute traces, and a final behavioral RL stage for chat and instruction following.[2][37] The release also introduced Markovian RSA, a test-time compute method that fuses the Markovian thinker idea (reasoning in fixed-length context chunks where only the tail of each chunk is passed forward) with parallel trace generation and recursive self-aggregation (RSA).[5] The result is that the model can run effectively unbounded chains of thought without ever overflowing a fixed context window, by carrying forward only a 4K-token tail between chunks and periodically aggregating partial traces.[3][5]
ZAYA1-8B benchmark results
The figures below are from the official Hugging Face model card, and were run on Zyphra's own evaluation harness.[6] The comparison models are Qwen3-4B-Thinking-2507, Qwen3.5-4B, and Gemma-4-E4B-it.[6]
On agentic benchmarks the model card reports lower relative scores: 39.22 on BFCL-v4 and 43.12 on tau-squared, below both Qwen models.[6] With Markovian RSA in its headline configuration (a 40K-token budget per rollout, with only a 4K-token tail carried forward between aggregation rounds), Zyphra reports 91.9 on AIME'25 and 89.6 on HMMT'25 (February).[37] The technical report notes that these test-time compute numbers were measured on a checkpoint taken before the final behavioral RL stage, and that comparator scores come from external sources; its comparison table lists GPT-5-High at 94.6 on AIME'25 and 88.3 on HMMT'25, figures it reproduces from DeepSeek's V3.2 report.[37] On that basis, Zyphra's release post and VentureBeat described the HMMT'25 result as exceeding GPT-5-High (89.6 versus 88.3); VentureBeat gave Claude Sonnet 4.5 a score of 79.2 on the same benchmark.[5][4] With "extra-high" test-time compute of about 5.5 million tokens per problem, the company reports that ZAYA1-8B outperforms DeepSeek-V3.2 and GPT-OSS-120B (high) on the APEX-shortlist mathematics benchmark.[5][2] VentureBeat wrote that the AIME'25 result closed the gap with models that have 30 to 50 times its active parameter count.[4]
The accompanying CEO statement framed the design philosophy directly. "ZAYA1-8B demonstrates what is possible when architecture, pretraining, and reinforcement learning are co-designed toward a single objective: maximizing the intelligence extracted per parameter and per FLOP," Puthalath said in the launch announcement.[2] The model was offered free of charge as a serverless endpoint on Zyphra Cloud at launch.[2] Zyphra's Hugging Face organization also hosts FP8 and MXFP4 expert-quantized variants of the model.[68]
ZAYA1-VL-8B
A vision-language variant, ZAYA1-VL-8B, was released on May 8, 2026 and builds on the ZAYA1-8B language model.[8][7] Zyphra's release post describes it as an MoE with 700 million active and 8 billion total parameters, while the technical report counts 9.2 billion total parameters and 1.4 billion active parameters including the vision encoder, which is taken from Qwen2.5-VL.[8][38][7] Two architectural choices distinguish it from the base model: vision-specific LoRA adapters integrated into the LLM rather than additional experts, which keeps the MoE structure intact, and bidirectional attention over image tokens to improve visual understanding.[38] The technical report says it is competitive with Molmo2-4B and InternVL3.5-4B and surpasses Qwen2.5-VL-3B, PLM-3B, and MolmoE-1B on a range of image understanding, reasoning, and counting benchmarks.[38] Zyphra said it was trained on roughly 140 billion tokens, far fewer than competing models, and only on open data.[8][7]
ZAYA1-74B-Preview
On May 7, 2026 Zyphra released ZAYA1-74B-Preview, an MoE with 4 billion active and 74 billion total parameters.[43] It is a reasoning-base checkpoint that had gone through pretraining, midtraining, and context extension but no RL post-training or chat tuning.[43] The architecture follows ZAYA1-8B, except that every other attention layer is replaced with a sliding window attention layer with a 4K window, both using CCA; Zyphra said this nearly halved KV-cache usage without hurting long-context benchmarks.[43] Pretraining covered about 15 trillion tokens, and three midtraining phases of about 1 trillion tokens each extended the context to 32K, 128K, and then 256K tokens, again on MI300X GPUs with Pensando Pollara networking.[43] Zyphra said at release that full-scale RL on AMD was under way and that it expected to release the final ZAYA1-74B model "in the coming weeks."[43] As of late October 2026, Zyphra's Hugging Face organization listed the preview checkpoint but no final ZAYA1-74B model.[68]
ZAYA1-8B-Diffusion-Preview
On May 14, 2026 Zyphra described ZAYA1-8B-Diffusion-Preview, an experiment in converting the autoregressive ZAYA1-8B base into a discrete diffusion language model.[44] Building on the TiDAR recipe, the company ran 600 billion tokens of diffusion-conversion midtraining at 32K context, extended the context to 128K over 500 billion tokens, and then ran a diffusion SFT phase.[44] The model generates blocks of 16 tokens at once; Zyphra reported a 4.6x speedup with a lossless sampler and 7.7x with a new logit-mixing sampler, and called it the first MoE diffusion model converted from an autoregressive LLM and the first diffusion language model trained on AMD.[44]
Training infrastructure
The ZAYA1 models were pretrained on the GPU cluster Zyphra built with IBM and AMD on IBM Cloud.[2][9] In its November 2025 description, Zyphra said the cluster had 128 nodes, each with eight AMD MI300X GPUs connected by AMD Infinity Fabric, for 1,024 GPUs in total; each GPU had a dedicated 400 Gbps Pollara network interface, the nodes were connected in a rails-only topology, and the cluster delivered more than 750 PFLOPs of real-world training performance.[40] The ZAYA1-8B announcement likewise said the model was pretrained on a cluster of 1,024 MI300X GPUs with Pensando Pollara interconnect.[2][36] An AMD case study published in August 2026 describes a larger configuration, 192 nodes with 1,536 MI300X GPUs, and quotes Millidge as saying Zyphra had trained about 20 trillion tokens on the cluster, with many uninterrupted 48-hour runs and one of about 72 hours.[59]
The MI300X is AMD's data center accelerator, with 192 GB of HBM3 memory per GPU.[59] Millidge told AMD that this capacity let the team train at up to 16K context without context parallelism.[59] The networking is Ethernet-based: Zyphra's November 2025 announcement described the cluster's "AMD Pensando networking (ethernet) interconnect."[41]
Zyphra's work on AMD hardware predates the IBM cluster. In December 2024 it published backward-pass kernels for FlashAttention-2 and Mamba2 on the MI300X, which it said were the first to surpass the H100 for those operations.[64] According to the AMD case study, Zyphra runs its own fork of Megatron-LM and has integrated kernels from AMD's AITER and Primus-Turbo libraries; Millidge said the team converted CUDA kernels to HIP with an automatic conversion tool and then spent most of its time optimizing them.[59]
Zyphra Cloud
Zyphra launched Zyphra Cloud on May 4, 2026, starting with Zyphra Inference, a serverless inference service for open-weight models such as DeepSeek V3.2, Kimi K2.6, and GLM 5.1.[45] The service runs on AMD Instinct MI355X GPUs on TensorWave's infrastructure and is aimed at long-context, agentic workloads such as coding agents and deep research.[45][70] Zyphra pointed to the MI355X's 288 GB of HBM3E per GPU as a reason for the choice, since more memory allows larger KV and prefix caches per node.[70] The company said the platform would later add RL and fine-tuning services, sandboxed agent environments on AMD EPYC CPUs, and dedicated GPU clusters.[45] Its Cloud page lists four components: the MAIA agent, agent environments, inference, and compute.[71]
On May 11, 2026, Zyphra announced 15 megawatts of MI355X capacity available through Zyphra Cloud, adding on-demand bare-metal GPU clusters and custom large-scale AMD deployments, and said it planned to support AMD's next-generation MI450 series.[46] "Zyphra Cloud is not just another AMD neocloud," Puthalath said in the announcement.[46] Forbes described the business as a "neocloud" that runs all of its hosting on AMD hardware.[49]
Zyphra has published its own inference benchmarks. Its first set, on May 18, 2026, compared its stack on a single MI355X node with AMD's baseline configuration and with NVIDIA's B200 on Kimi K2.6, GLM-5.1, and DeepSeek V3.2.[47] The company reported that the B200 still outperformed both its stack and the AMD baseline for single requests across all three models, with the gap narrowing at longer context lengths, where its Tensor and Sequence Parallelism (TSP), Tree Attention, and communication-overlap methods matter more.[47] A second round of optimizations, published on October 20, 2026, added custom HIP kernels for MoE layers and sparse attention to Zyphra's forks of vLLM and SGLang, packaged as the Zyphra Optimization Engine (ZOE).[48] Zyphra reported that ZOE sped up GLM-5.3 time to first token at 512K tokens of context by 2.8x with no prefix-cache hits and 3.6x at a 90% hit rate, and raised DeepSeek-V4-Pro single-user decode throughput at 1 million tokens of context by 1.40x.[48]
Datasets: Zyda and Zyda-2
Zyphra also publishes large open pretraining datasets under the Zyda brand. The original Zyda was released in June 2024 as a 1.3 trillion token dataset, built by filtering and deduplicating across RefinedWeb, Starcoder, C4, the Pile, SlimPajama, peS2o, and arXiv.[28][30] The accompanying paper (arXiv:2406.01981) reports that models trained on Zyda outperform models trained on any individual source dataset at comparable scale.[28]
Zyda-2 followed in October 2024 and expanded the corpus to 5 trillion tokens, incorporating DCLM, FineWeb-Edu, and the Common Crawl portion of Dolma v1.7.[29][31] The data pipeline was rebuilt using NVIDIA's NeMo Curator, a GPU-accelerated curation library, which cut total processing time from roughly three weeks to two days.[29] Models trained on Zyda-2 outperform identical models trained on the Pile, RefinedWeb, FineWeb, FineWeb-Edu, or DCLM individually.[29] Both datasets are available on the Zyphra Hugging Face organization under the ODC-By license.[30][31] In September 2026 Zyphra released PUFFER, an open-source incremental fuzzy-deduplication system for growing training corpora, which it said was deployed in production on more than 30 billion documents.[58]
Zonos text-to-speech
In February 2025 Zyphra extended its open-model strategy beyond text with the beta release of Zonos-v0.1, a pair of 1.6B parameter text-to-speech models.[32][33] One uses a standard transformer architecture; the other is an SSM hybrid based on Mamba2, which Zyphra described as the first open-source SSM model available for TTS.[33] Both were trained on roughly 200,000 hours of speech, primarily English with substantial Chinese, Japanese, French, Spanish, and German content.[32][33]
Zonos generates audio natively at 44 kHz and supports voice cloning from reference clips of 5 to 30 seconds.[33][34] The models accept conditioning inputs for speaking rate, pitch, audio quality, and emotion.[34] Zyphra released the model weights on Hugging Face under the Apache 2.0 license and said the model's expressiveness and quality were on par with, or better than, top TTS providers.[33][34]
ZONOS2 followed on June 12, 2026. It is a sparse MoE text-to-speech model with 900 million active and 8 billion total parameters, released under Apache 2.0 and built on a variant of the MoE++ architecture used in the ZAYA language models; Zyphra called it the first open-source MoE TTS model.[53] Its model card says it was trained on more than 6 million hours of multilingual speech, with English, Mandarin Chinese, and Japanese in its top language tier.[54] Zyphra introduced a new evaluation, ZTTS1-Eval, alongside the release, and said it had chosen to emphasize fidelity to the source voice over the lowest possible word error rate.[53] The model was served free of charge on Zyphra Cloud for a promotional period after release.[53]
ZUNA brain-signal models
On February 18, 2026 Zyphra released ZUNA, its first foundation model trained on brain data: a 380-million-parameter diffusion autoencoder that denoises, reconstructs, and upsamples scalp EEG signals across arbitrary channel layouts.[51] The company trained it on roughly 2 million channel-hours of EEG from public sources, encoded electrode positions and time with a 4-D rotary position embedding, and reported that it outperformed spherical spline interpolation, the default method in the widely used MNE package, by a margin that grew as more channels were dropped.[51] Zyphra presents ZUNA as an early step toward noninvasive "thought-to-text" brain-computer interfaces; Forbes described it as a model "designed to decode brainwave activity."[51][49] ZUNA1.1, released on July 16, 2026, accepts variable-length inputs of 0.5 to 30 seconds and can reconstruct arbitrary intervals within channels as well as whole channels; its technical report appeared on arXiv on July 29, 2026.[52][58] Both models are released under Apache 2.0.[51][52]
Other research
Zyphra publishes a steady stream of shorter research results. Before 2025 these included NeuraNoC, a neuroscience-inspired network-on-chip design (November 2023), a CPU-based retrieval system it said extended off-the-shelf LLMs to a billion tokens of context (October 2024), and the Mixture-of-PageRanks retriever (December 2024).[58] Selected 2026 work is listed below.
| Date | Work | Summary (as described by Zyphra) |
|---|---|---|
| February 5, 2026 | Online Vector-Quantized (OVQ) attention | Sequence-mixing layer aiming for a better balance between memory and compute costs and long-context ability[58] |
| March 25, 2026 | Hybrid Associative Memory (HAM) | KV cache stores only the tokens an RNN fails to predict[58] |
| May 4, 2026 | Tensor and Sequence Parallelism (TSP) | Folds tensor and sequence parallelism onto one device axis for long-context training and serving[58] |
| May 22, 2026 | Equilibrium propagation beyond energy-based models | Extends a local learning rule to skew-gradient systems such as FitzHugh-Nagumo neurons[58] |
| May 29, 2026 | Communication overlap on AWS Inferentia2 | With AWS; Domino-style tensor-parallel overlap in the Neuron stack, tested on Llama 3-8B[58] |
| June 16, 2026 | Norm-Agnostic residual network (NAG) | Splits the residual stream into norm and direction lanes, enabling adaptive layer skipping[58] |
| June 24, 2026 | Plasticity loss in continual learning | Decoder-only transformers of 5M to 314M parameters lose the ability to learn under continued training[58] |
| September 1, 2026 | PUFFER | Incremental fuzzy deduplication, 11x to 35x faster than CPU baselines in Zyphra's tests[58] |
| October 1, 2026 | Position learning in hybrid NoPE models | Local layers create a recency bias that global attention without position encoding learns to read[58] |
| October 8, 2026 | Expert coupling in MoE pretraining | Correlated expert placement and token shuffling cut all-to-all time by up to 2.63x on MI300X[58] |
Maia
Maia (styled MAIA on the company's site) is Zyphra's agent product. A 2024 version of the company's About page described "MaiaOS, a multimodal agent system."[61] IBM's October 2025 announcement said Zyphra would use the IBM Cloud cluster to develop multimodal foundation models across language, vision, and audio "to power Maia, a general purpose superagent designed to deliver productivity benefits for knowledge workers across enterprise."[9] Zyphra's agent page now describes MAIA as "a general, open superagent for teams," with shared context, persistent memory, and interaction through language, audio, and vision, and says it orchestrates open foundation models.[69] When connected to a Google account, it can read and organize information from Gmail, Google Calendar, and Google Drive within the permissions a user grants.[69]
Reception and significance
The original Zamba release drew coverage focused on its potential to run capable models on local devices; Puthalath told VentureBeat at the time that "the root problem is that AI from the big companies is centralized."[35] The Tree Attention paper positioned the method as a faster alternative to Ring Attention for distributed decoding of long contexts.[24]
Coverage of ZAYA1-8B emphasized two themes. First, that a model with fewer than one billion active parameters could be competitive with first-generation reasoning models such as DeepSeek-R1-0528 and Gemini 2.5 Pro on hard mathematics benchmarks.[3][4] Second, that its pretraining ran entirely on AMD hardware, which VentureBeat called "the real headline" and evidence that AMD's platform is a viable alternative to NVIDIA's for model developers.[4] VentureBeat reported that the announcement drew nearly one million views on X within 24 hours, and highlighted the RL cascade and a technique Zyphra calls Router Replay, which records expert choices made during generation so that the trainer uses the same routing.[4] The company's own figures carry caveats: the headline test-time compute results were measured on a pre-final checkpoint against comparator scores taken from other publications, and the model trails similarly sized models on agentic benchmarks.[37][6]
Forbes placed Zyphra among U.S. startups that investors were funding as alternatives to DeepSeek, naming Reflection AI as a rival.[49] Debarghya Das's "Ultimate Neolab List" includes Zyphra and classifies it as a "Clean" case of a neolab: a research team training its own models, with little disclosed revenue, heavy compute, and big raises.[67]
Most of Zyphra's models, weights, and inference code have been released under Apache 2.0 or similarly permissive licenses, without commercial use restrictions.[6][58] Zyphra has framed this as central to its identity, arguing that intelligence should not be controlled by a small number of companies.[1]
Architectural innovations summary
The through-line of Zyphra's technical work is reducing the cost of intelligence per parameter and per FLOP, often by changing the building blocks rather than scaling up. The list below summarizes the company's named contributions and where they appear.
| Innovation | Year | Description | First used in |
|---|---|---|---|
| Mamba-MoE hybrid | 2024 | Mamba SSM blocks combined with mixture-of-experts layers | BlackMamba[56] |
| Shared attention block | 2024 | A single attention block whose weights are reused across the network | Zamba-7B[15] |
| Mamba2 hybrid backbone | 2024 | Mamba2 SSM layers interleaved with shared attention | Zamba2 family[20] |
| LoRA projectors on shared blocks | 2024 | Per-invocation low-rank adapters for depth specialization | Zamba2 family[20] |
| Tree Attention | 2024 | Tree-reduction parallelization of attention across GPUs | Zyphra Inference stack[24][47] |
| Compressed Convolutional Attention | 2025 | Attention in a shared low-rank latent with sequence convolution | ZAYA1-base, ZAYA1-8B[27][42] |
| MoE++ architecture recipe | 2026 (components previewed in ZAYA1-base, 2025) | CCA, MLP router with PID balancing, learned residual scaling | ZAYA1-8B[37][42] |
| Markovian RSA | 2026 | Recursive self-aggregation over fixed-length reasoning chunks | ZAYA1-8B[5] |
| Vision-specific LoRA and bidirectional image attention | 2026 | Modality-specific capacity inside an MoE vision-language model | ZAYA1-VL-8B[38] |
Continue reading
- ZAYA1-8BZAYA1-8B is an open-weight, reasoning-focused Mixture-of-Experts (MoE) large language model released by San Francisco-based AI research lab Zyphra on May 6, 2026.Mentioned 25 times above
- MambaMamba is a neural network architecture for sequence modeling that uses selective state space models (SSMs) to process sequential data in linear time with respect to sequence lengthMentioned 10 times above
- State space model (deep learning)A state space model (SSM) in deep learning is a class of sequence model that maps an input sequence to an output sequence through a fixed-size latent stateMentioned 3 times above
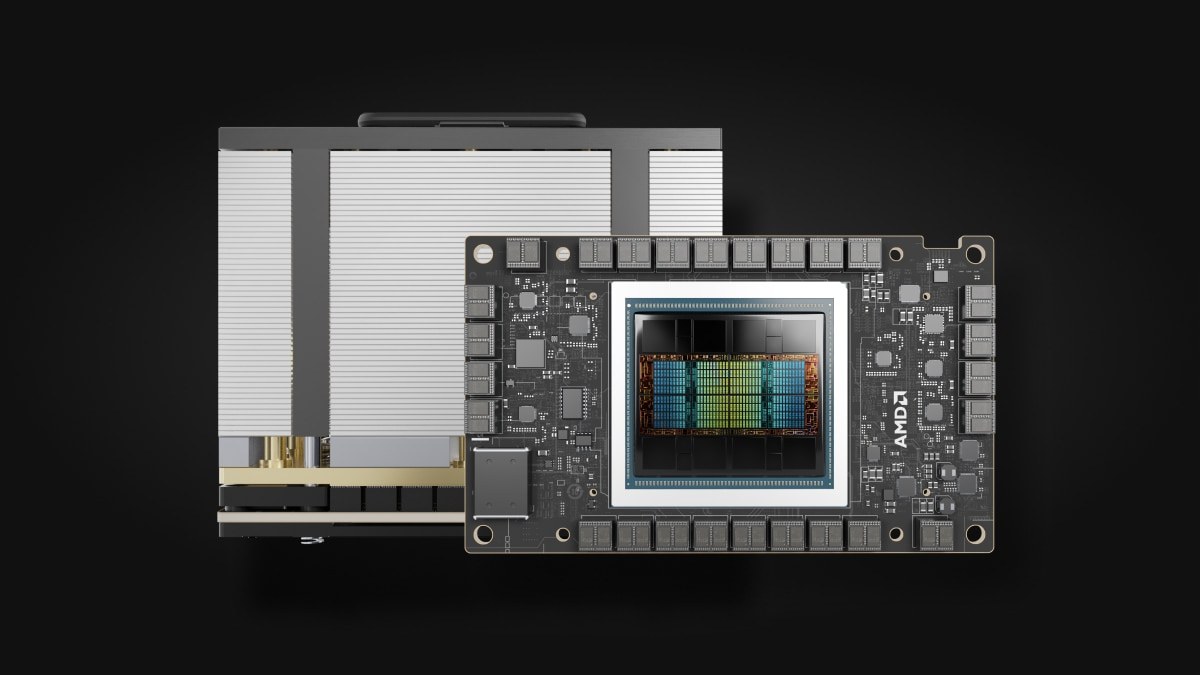
- AMD Instinct MI300XThe AMD Instinct MI300X is a data center GPU accelerator that Advanced Micro Devices released on December 6, 2023, built on the CDNA 3 architecture and paired with 192 GB of HBM3 memory at 5.3 TB/s of bandwidthMentioned 3 times above
- NeolabA neolab, also written neo-lab or NeoLab, is an informal term for an AI research company organized around a technical research program.Mentioned 3 times above
- NeocloudA neocloud is a cloud computing company whose business is renting out GPU capacity for artificial intelligence workloads, rather than selling the broad catalogue of storage, database, networking and…Mentioned twice above
More from See also
More to read
Topics:AI CompaniesLarge Language ModelsMixture of ExpertsOpen Source AI
References
- ^1 ^2 ^3 ^4 ^5 ^6Zyphra company overview, About page. zyphra.com/about
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8"Zyphra Releases ZAYA1-8B, a Reasoning Model trained on AMD and Optimized for Maximum Intelligence Density per Parameter," PR Newswire, May 6, 2026. prnewswire.com/...-density-per-parameter-302764700
- ^1 ^2"Zyphra Releases ZAYA1-8B: A Reasoning MoE Trained on AMD Hardware That Punches Far Above Its Weight Class," MarkTechPost, May 6, 2026. marktechpost.com/...hes-far-above-its-weight-class
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12"Meet ZAYA1-8B, a super efficient, open reasoning model trained on AMD Instinct MI300 GPUs," VentureBeat, May 2026. venturebeat.com/...ined-on-amd-instinct-mi300-gpus
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12"ZAYA1-8B: Frontier intelligence density, trained on AMD," Zyphra release post, May 6, 2026. zyphra.com/...zaya1-8b
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9ZAYA1-8B model card, Hugging Face. huggingface.co/...ZAYA1-8B
- ^1 ^2 ^3 ^4ZAYA1-VL-8B model card, Hugging Face. huggingface.co/...ZAYA1-VL-8B
- ^1 ^2 ^3ZAYA1-VL-8B release post, Zyphra, May 8, 2026. zyphra.com/...zaya1-vl-8b
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13"IBM and AMD Collaborate with Zyphra on Next Generation AI Infrastructure," IBM newsroom, October 1, 2025. newsroom.ibm.com/...t-generation-ai-infrastructure
- ^"AI research and product company Zyphra signs deal for large AMD MI300X cluster on IBM Cloud," Data Center Dynamics. datacenterdynamics.com/...00x-cluster-on-ibm-cloud
- ^1 ^2 ^3 ^4Sri Muppidi, "Open-Source AI Startup Zyphra Targets $1 Billion Valuation," The Information, January 31, 2025. theinformation.com/...-targets-1-billion-valuation
- Zyphra company profile, Crunchbase. crunchbase.com/...zyphra-technologies
- Krithik Puthalath profile, Crunchbase. crunchbase.com/...krithik-puthalath
- ^1 ^2Beren Millidge personal site. beren.io/aboutme
- ^1 ^2 ^3 ^4 ^5 ^6 ^7"Zamba: A Compact 7B SSM Hybrid Model," arXiv:2405.16712, Glorioso, Anthony et al., May 2024. arxiv.org/...2405.16712
- ^1 ^2 ^3 ^4 ^5"Zamba-7B," Zyphra release post, April 16, 2024. zyphra.com/...zamba
- ^1 ^2 ^3 ^4 ^5"Zamba2-7B," Zyphra release post, October 14, 2024. zyphra.com/...zamba2-7b
- ^1 ^2 ^3"Zamba2-mini (1.2B)," Zyphra release post, August 27, 2024. zyphra.com/...zamba2-mini
- ^1 ^2 ^3"Zamba2-small (2.7B)," Zyphra release post, July 28, 2024. zyphra.com/...zamba2-small
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10"The Zamba2 Suite: Technical Report," arXiv:2411.15242, Glorioso, Anthony, Tokpanov et al., November 2024. arxiv.org/...2411.15242
- ^Zamba2-7B model card, Hugging Face. huggingface.co/...Zamba2-7B
- ^1 ^2Zamba2-2.7B model card, Hugging Face. huggingface.co/...Zamba2-2.7B
- ^1 ^2 ^3Zamba2-1.2B model card, Hugging Face. huggingface.co/...Zamba2-1.2B
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10"Tree Attention: Topology-aware Decoding for Long-Context Attention on GPU clusters," arXiv:2408.04093. arxiv.org/...2408.04093
- ^1 ^2 ^3 ^4"Tree Attention: Topology-aware Decoding for Long-Context Attention on GPU Clusters," Zyphra release post. zyphra.com/...ng-context-attention-on-gpu-clusters
- ^1 ^2Tree Attention reference implementation. github.com/...tree_attention
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14"Compressed Convolutional Attention: Efficient Attention in a Compressed Latent Space," arXiv:2510.04476, Figliolia, Alonso, Iyer, Anthony, Millidge, October 2025. arxiv.org/...2510.04476
- ^1 ^2 ^3 ^4 ^5"Zyda: A 1.3T Dataset for Open Language Modeling," arXiv:2406.01981. arxiv.org/...2406.01981
- ^1 ^2 ^3"Train Highly Accurate LLMs with the Zyda-2 Open 5T-Token Dataset Processed with NVIDIA NeMo Curator," NVIDIA Technical Blog. developer.nvidia.com/...d-with-nvidia-nemo-curator
- ^1 ^2 ^3 ^4Zyda dataset, Hugging Face. huggingface.co/...Zyda
- ^1 ^2 ^3Zyda-2 dataset, Hugging Face. huggingface.co/...Zyda-2
- ^1 ^2"Zyphra Introduces the Beta Release of Zonos: A Highly Expressive TTS Model with High Fidelity Voice Cloning," MarkTechPost, February 10, 2025. marktechpost.com/...th-high-fidelity-voice-cloning
- ^1 ^2 ^3 ^4 ^5 ^6"Beta Release of Zonos-v0.1," Zyphra release post, February 10, 2025. zyphra.com/...beta-release-of-zonos-v0-1
- ^1 ^2 ^3Zonos repository, GitHub. github.com/...Zonos
- ^1 ^2 ^3"Zyphra releases Zamba, an SSM-hybrid foundation model to bring AI to more devices," VentureBeat, April 2024. venturebeat.com/...del-to-bring-ai-to-more-devices
- ^"Zyphra Releases ZAYA1-8B Reasoning Model," HPCwire (AIwire), May 7, 2026 (republished press release). hpcwire.com/...a-releases-zaya1-8b-reasoning-model
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Washbourne, R., Iyer, R., Figliolia, T., et al. "ZAYA1-8B Technical Report," arXiv:2605.05365, May 6, 2026. arxiv.org/...2605.05365
- ^1 ^2 ^3 ^4 ^5Shapourian, H., Hejazi, K., Sule, O. M., Millidge, B. "ZAYA1-VL-8B Technical Report," arXiv:2605.08560, May 8, 2026. arxiv.org/...2605.08560
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Anthony, Q., Tokpanov, Y., et al. "Training Foundation Models on a Full-Stack AMD Platform: Compute, Networking, and System Design," arXiv:2511.17127, November 21, 2025. arxiv.org/...2511.17127
- ^1 ^2 ^3"ZAYA1 - Pretraining on Integrated AMD Platform: Compute, Network, and System Design," Zyphra, November 24, 2025. zyphra.com/...zaya1
- ^1 ^2 ^3 ^4"Zyphra Demonstrates First Large Scale Training on Integrated AMD Compute and Networking Powered by IBM Cloud," Zyphra press release, November 24, 2025. zyphra.com/...ck-amd-platform-powered-by-ibm-cloud
- ^1 ^2 ^3 ^4 ^5 ^6ZAYA1-base model card, Hugging Face. huggingface.co/...ZAYA1-base
- ^1 ^2 ^3 ^4 ^5 ^6"ZAYA1-74B-Preview: Scaling Pretraining on AMD," Zyphra, May 7, 2026. zyphra.com/...zaya1-74b-preview
- ^1 ^2 ^3 ^4"ZAYA1-8B-Diffusion-Preview: Efficient Parallel Decoding on AMD," Zyphra, May 14, 2026. zyphra.com/...zaya1-8b-diffusion-preview
- ^1 ^2 ^3 ^4 ^5 ^6"Zyphra and AMD Partner to Power Zyphra Cloud on AMD Instinct MI355X GPUs," PR Newswire, May 4, 2026. prnewswire.com/...d-instinct-mi355x-gpus-302761765
- ^1 ^2"Zyphra Announces 15 Megawatts of AMD Instinct MI355X GPU Capacity Through Zyphra Cloud," Zyphra, May 11, 2026. zyphra.com/...5x-gpu-capacity-through-zyphra-cloud
- ^1 ^2 ^3 ^4"Benchmarking Zyphra Inference: Production Performance on MI355X," Zyphra, May 18, 2026. zyphra.com/...nce-production-performance-on-mi355x
- ^1 ^2"Zyphra Inference Wave 2: Faster MoE and Long-Context Serving on MI355X," Zyphra, October 20, 2026. zyphra.com/...zyphra-inference-wave2
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Anna Tong, "Artificial Intelligence Lab Zyphra Raising $500 Million To Challenge Nvidia Dominance," Forbes, May 19, 2026. forbes.com/...illion-to-challenge-nvidia-dominance
- ^"AI model developer Zyphra raising $500 million at $5 billion valuation in funding round that includes commitment from AMD - Forbes," Reuters (via TradingView), May 19, 2026. tradingview.com/...udes-commitment-from-amd-forbes
- ^1 ^2 ^3 ^4 ^5 ^6"ZUNA: BCI Foundation Model Advancing Towards Thought-to-Text," Zyphra, February 18, 2026. zyphra.com/...zuna
- ^1 ^2 ^3Warner, C., Mago, J., Huml, J., Millidge, B. "ZUNA1.1: A more flexible EEG foundation model for Denoising and Super-resolution," arXiv:2607.27308, July 29, 2026. arxiv.org/...2607.27308
- ^1 ^2 ^3 ^4"ZONOS2: Real-time TTS with High-Fidelity Voice Cloning," Zyphra, June 12, 2026. zyphra.com/...zonos2
- ^ZONOS2 model card, Hugging Face. huggingface.co/...ZONOS2
- ^1 ^2"Zamba2-VL: Hybrid SSM Vision-Language Models," Zyphra, June 2, 2026. zyphra.com/...zamba2-vl
- ^1 ^2 ^3 ^4Anthony, Q., Tokpanov, Y., Glorioso, P., Millidge, B. "BlackMamba: Mixture of Experts for State-Space Models," arXiv:2402.01771, February 2024. arxiv.org/...2402.01771
- ^1 ^2ZR1-1.5B model card, Hugging Face. huggingface.co/...ZR1-1.5B
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20"Our Work" (Zyphra research, model and press index). zyphra.com/our-work (accessed October 27, 2026)
- ^1 ^2 ^3 ^4 ^5 ^6 ^7"Zyphra Trains Advanced Reasoning Models at Scale with AMD," AMD case study, August 19, 2026. amd.com/...nced-reasoning-models-at-scale-with-amd
- ^1 ^2 ^3 ^4Beren Millidge, curriculum vitae. beren.io/CV.pdf
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Zyphra About page (team listing), archived by the Internet Archive on September 5, 2024. web.archive.org/...about
- ^1 ^2Zamba-7B-v1 model card, Hugging Face. huggingface.co/...Zamba-7B-v1
- ^"Anthropic raises $124 million to build more reliable, general AI systems," Anthropic, May 28, 2021. anthropic.com/...-more-reliable-general-ai-systems
- ^Quentin Anthony, "Frontier Training Kernels for Transformers (FA2) and SSMs (Mamba2) on AMD Instinct MI300X Accelerators," Zyphra, December 10, 2024. zyphra.com/...mers-and-hybrid-models-on-amd-mi300x
- ^Xindongxi (芯东西, republished by 36Kr), report on Zyphra's fundraising and Zyphra Cloud (Chinese), May 20, 2026. eu.36kr.com/...3817228046894209
- ^1 ^2"Zyphra Technologies" company profile, Dealroom. dealroom.co/...zyphra-technologies (accessed October 27, 2026)
- ^1 ^2 ^3 ^4Debarghya Das, "The Ultimate Neolab List." debarghyadas.com/neolabs (accessed October 27, 2026)
- ^1 ^2Zyphra organization page, Hugging Face. huggingface.co/Zyphra (accessed October 27, 2026)
- ^1 ^2"MAIA," Zyphra agent page. zyphra.com/agent
- ^1 ^2"The Zyphra Inference Cloud: AMD-First Inference for Long-Context, Agentic Workloads," Zyphra, May 4, 2026. zyphra.com/...the-zyphra-inference-cloud
- ^"Zyphra Cloud," Zyphra. zyphra.com/cloud
- ^BlackMamba-2.8B model card, Hugging Face. huggingface.co/...BlackMamba-2.8B
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions · v7 · 7,394 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Models, benchmarks, training infrastructure, locations and funding reports checked against Zyphra's site and technical reports, AMD and IBM releases, and Forbes and The Information coverage, October 2026.
Cite this page: AI Wiki. "Zyphra." aiwiki.ai, updated 28 Oct 2026, fact-checked 27 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/zyphra